Free. You pay your AI provider directly.
There is no plan to choose and no card to enter. You connect your own AI key, and the provider bills you for what you use at their own prices. Or you let Claude draft on your own Claude plan, without any key.
The plan
€0
per month, no card
Included
- Up to 3 workspaces per account
- Up to 3 mailboxes per workspace
- Up to 200 documents and 500 MB of knowledge per workspace
- Unlimited team members
- All features, in English and Dutch
- Export of all your workspace data at any time
01Two modes
Two ways to get drafts
- A
Automatic, with your own API key
Every new email is sorted and gets a cited reply draft right away. Your AI provider bills you per use; see the estimates below.
- B
On demand, through Claude on your Claude plan
Add Nearlysent as a custom connector in Claude and ask Claude to draft replies when you want them. No API key and no extra cost here; it uses your Claude plan. New mail is not sorted automatically in this mode.
Either way, a person reviews and sends every email in the app. You can use both.
02Cost per email
What does one email cost?
An estimate of what your AI provider charges to sort one incoming email and write one reply draft, computed from the price list the app itself uses.
| Provider | Sorting model | Draft model | Per email | Per 1,000 emails |
|---|---|---|---|---|
| Anthropicbudget | Claude Haiku 5.5 | Claude Haiku 5.5 | $0.0007 | $0.725 |
| Anthropicrecommended | Claude Haiku 5.5 | Claude Sonnet 5.5 | $0.010 | $10.22 |
| Anthropichighest quality | Claude Haiku 5.5 | Claude Opus 5.5 | $0.020 | $20.23 |
| OpenAIbudget | GPT-6 Luna | GPT-6 Luna | $0.0007 | $0.725 |
| OpenAIrecommended | GPT-6 Luna | GPT-6.1 Sol | $0.010 | $10.22 |
| OpenAIhighest quality | GPT-6 Luna | GPT-6 Astra | $0.050 | $50.23 |
| Your own server (e.g. Ollama)you pay for the hardware | Any local model | Any local model | $0 | $0 |
Assumptions
- 1.Sorting: about 1,500 input tokens and 150 output tokens per email.
- 2.Draft: about 3,000 input tokens (instructions, the email and the relevant document passages) and 400 output tokens.
- 3.Prompt caching is ignored, so real costs are usually lower. Long threads, rewrites and chat cost extra; skipped newsletters and auto-replies cost nothing.
Prices checked 2026-10-23
03Spending cap
A cap on your AI spending.
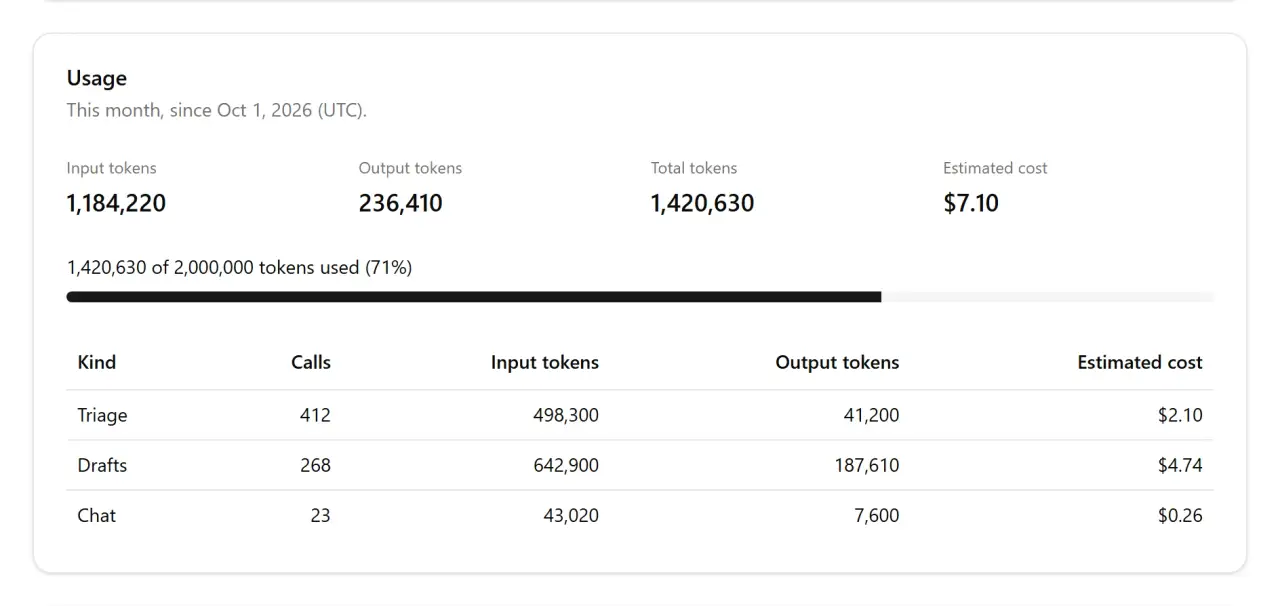
Each workspace has a monthly token cap. When it is reached, the assistant stops calling the AI until the next month or until you raise the cap. The usage page shows tokens and estimated cost per draft and per month.
Need something custom?
An integration with your own systems, a hosted instance or a different workflow.